
When a Retrieval-Augmented Generation (RAG) application fails in production, the blame usually falls on the Large Language Model (LLM). “The model hallucinated,” we say.
But in enterprise environments, the model is rarely the culprit. The retrieval layer feeding the LLM is often what causes the failure.
This failure pattern is called Context Drift: the state where retrieved context is either factually obsolete (stale) or semantically imprecise (noise). It actively misleads the model into generating a confident but incorrect answer.
Look, RAG isn’t just a model architecture. It’s a data dependency problem. If the data pipeline feeding your vector database relies on slow batch processing or lacks semantic precision, your answers will inevitably drift from reality.
For architects and data engineers, fixing context drift means shifting focus from “prompt engineering” to “data engineering.” Specifically, how fresh and governed is your data before it ever reaches the model?
TL;DR
Context drift in RAG happens when retrieved context is outdated (stale) or semantically wrong (irrelevant noise), causing “grounded” hallucinations.
Stale-context drift usually results from batch ETL that updates the vector index hours later than the source of truth.
Relevance drift comes from poor chunking/embeddings and missing metadata + governance, so “similar” results aren’t actually correct.
Fix drift by moving retrieval pipelines from batch to real-time streaming (CDC → Kafka → stream processing → vector DB) and attaching version/time/entity metadata.
Track Mean Time to Index (MTTI) and add traceability + instant deletes (tombstones) to keep RAG accurate and compliant.
What is context drift in RAG?
Context Drift refers to the divergence between the current state of reality (operational data) and the state of knowledge provided to an AI model (vector data). It happens when your retrieval system grounds the LLM’s answer in context that’s factually obsolete or semantically imprecise.
To understand context drift, you need to distinguish it from “pure hallucination.”
Pure Hallucination: The model invents facts because it lacks knowledge. Think: inventing a court case that never happened.
Context Drift (Grounded Error): The model behaves correctly by analyzing the provided context, but the context itself is flawed. Think: summarizing a refund policy that was valid yesterday but updated four hours ago.
Context drift silently kills enterprise RAG systems because the errors are harder to detect. The LLM’s response looks authoritative, grounded, and may even cite sources.
The model isn’t making things up. It’s accurately reporting on a version of the truth that no longer exists.
What causes context drift in RAG?
Context drift shows up in two distinct ways: Stale-Context Drift (a failure of time) and Relevance Drift (a failure of precision). Both are symptoms of architectural flaws in how you’re ingesting data.
Stale-context drift: when your vector index is out of date
Stale-context drift happens when your vector database is out of sync with your operational database. This lag creates a blind spot where the AI has no idea about recent events.
This isn’t a rare edge case. A 2024 study on dynamic corpora found that 42.3% of retrieved document sets contained temporally conflicting information, directly correlating to a 31.2% contradiction rate in generated answers.
In high-velocity environments like finance or inventory management, even a small window of staleness can be catastrophic.
The Root Cause: The Batch Bottleneck
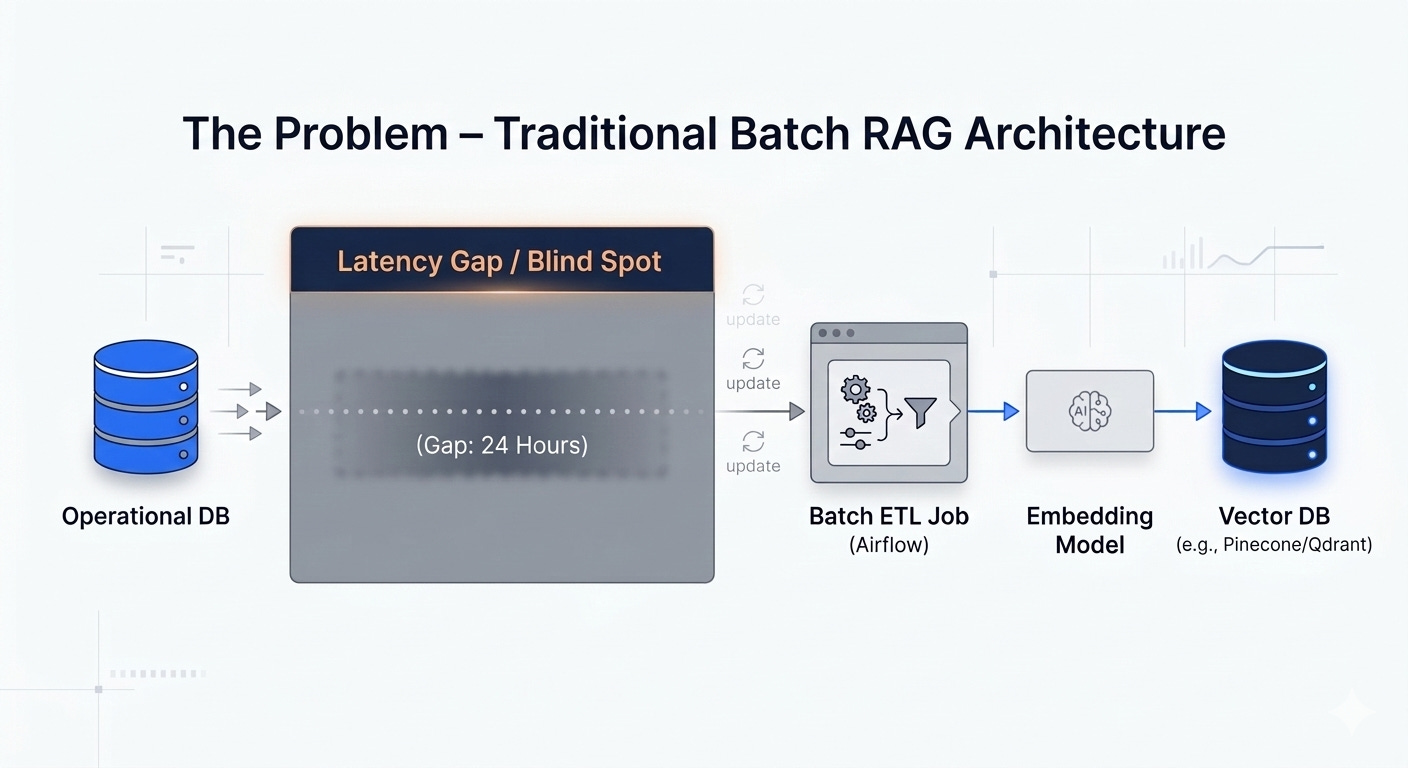
Reliance on periodic batch jobs (ETL) to update vector stores is the primary driver of stale drift.
Most RAG architectures use a “snapshot and sync” approach:
Extract data from a source (e.g., Snowflake, PostgreSQL) once every 24 hours.
Chunk and embed the data.
Upsert the data into a vector database (e.g., Pinecone, Milvus).
This architecture guarantees that the context provided to the LLM always lags behind reality. If a policy changes at 9:00 AM and your batch job runs at midnight, your RAG system will provide incorrect answers for 15 hours.
Relevance drift: when retrieval returns the wrong context
Relevance drift happens when retrieved chunks are semantically close to the query but contextually wrong. Your vector search returns “nearest neighbors” that are mathematically similar but logically irrelevant.
Root Cause 1: ‘Black Box’ Embedding
Traditional pipelines often treat embedding models as black boxes, dumping raw, unprocessed text into them. Garbage in, garbage out.
This fails because standard embedding models can’t distinguish between similar-sounding but distinct concepts without explicit guidance. A query about “Python setup” might retrieve a chunk about “Python snake habitats” if the embedding model lacks domain awareness.
Root Cause 2: Lack of Governance
Without schema enforcement or data lineage, debugging relevance drift becomes nearly impossible. When a bad answer gets generated, engineers often can’t trace it back to a specific version of a source document or understand what transformations occurred.
Did the chunk come from the Draft version of the document or the Final version? Without governed data pipelines that preserve this metadata, your retrieval layer becomes a chaotic swamp of unverified information.
Honestly, both forms of drift stem from the same architectural mismatch: you’re treating data as a static lake to be polled, when enterprise data is actually a fluid, continuous stream of events.
Examples of context drift in production RAG systems
Here’s how these drift patterns play out in live scenarios:
Scenario 1: Financial Fraud Detection (Stale Drift)
A financial services firm used RAG to assist fraud analysts. A compromised account was flagged in the operational database, but the vector index update was scheduled for a nightly batch. Because of this 45-minute lag, the RAG-powered automated review system approved $12,400 in fraudulent transactions because it retrieved the “clean” account status from the stale vector store. The AI acted correctly based on the data it had. But the data was wrong.
Scenario 2: E-commerce Inventory Bot (Stale Drift)
A customer asks a shopping bot, “Is the ‘AeroWidget Pro’ in stock?” The bot queries a vector index updated two hours ago and confidently replies, “Yes, it’s available!” But a flash sale caused the item to sell out an hour prior. The “Out of Stock” event in the operational database hadn’t propagated to the vector index yet. The result: a failed checkout, a frustrated customer, and a refund request.
Scenario 3: Internal HR Policy Bot (Stale & Relevance Drift)
An employee asks, “What is the work-from-home policy for 2024?” The retrieval system pulls a chunk from “2023 Policy.pdf” because the keyword match is strong and the file hasn’t been archived. Meanwhile, “2024 Policy.pdf” was uploaded yesterday but hasn’t been indexed yet because of a failed batch job. The bot confidently states the outdated mandatory office days, causing internal confusion.
Scenario 4: Financial Market Analyst (Relevance Drift)
An analyst asks a research tool to “Summarize market sentiment for AAPL.” The system retrieves recent news, but one retrieved chunk refers to a different company with the ticker ‘AAPL’ listed on a foreign exchange, or perhaps a supplier named “Apple Inc.” (unrelated to the tech giant). The embedding model failed to distinguish the entities. The LLM incorporates this irrelevant noise into its summary, skewing the sentiment analysis negative based on unrelated news.
How to prevent context drift with real-time streaming RAG
The solution to context drift isn’t a better prompt. It’s a faster, smarter data pipeline.
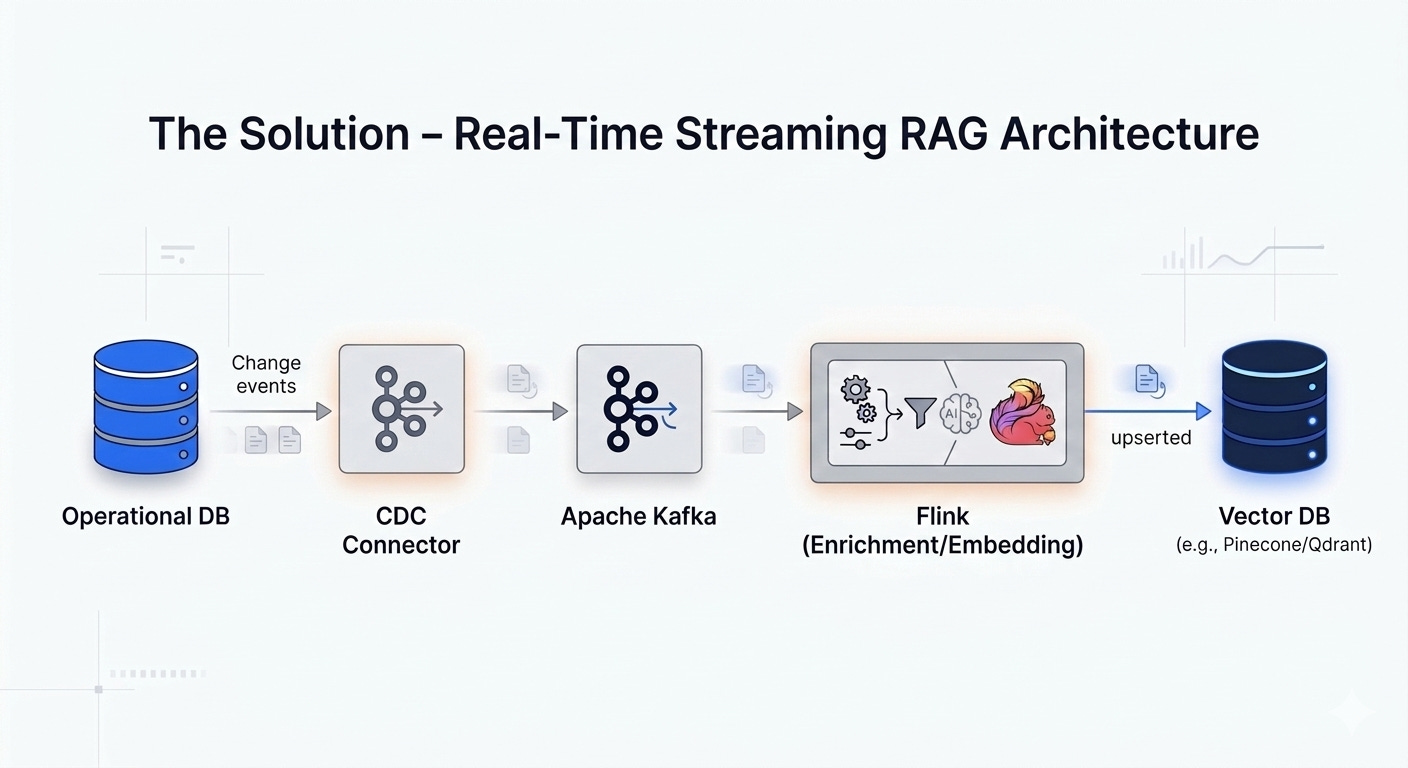
By shifting from batch ETL to real-time data streaming, you eliminate the latency gap and ensure the retrieval layer mirrors the operational state of your business.
Batch vs. streaming RAG architecture (where drift happens)
Use event-driven updates to reduce stale-context drift
Move from periodic polling to event-driven architectures using tools like Apache Kafka. Instead of asking, “What changed in the last 24 hours?”, your system reacts to every single change event.
When a source record gets updated (say, an inventory count changes), a Change Data Capture (CDC) connector immediately streams that event to a topic. This event triggers a real-time embedding process that updates the vector database within seconds. Not hours.
Use stream processing to improve retrieval relevance
Raw data is rarely ready for retrieval. Use stream processing engines like Apache Flink to clean, enrich, and format data before embedding.
Entity Extraction: Use lightweight NLP models within the stream to identify key entities (products, user IDs) and tag them as structured metadata.
Metadata Inheritance: Make sure chunks inherit critical context from their parent documents. A chunk describing a “cancellation policy” is useless without the metadata document_version: v2024 and region: EU. Stream processing attaches this metadata to every chunk payload, enabling precise filtering during retrieval.
Govern embeddings with schemas, lineage, and data contracts
Treat your vector embeddings as a “Data Product.” Use a Schema Registry to strictly enforce the structure of data entering your AI pipeline.
If a source system changes its date format, the Schema Registry catches the incompatibility before it breaks your downstream indexing application.
Propagate deletes to the vector database for GDPR compliance
One of the hardest challenges in RAG is handling deletions. If a user exercises their Right to Erasure (GDPR), you can’t wait for a weekly purge.
Using CDC tools like Debezium, a database delete operation generates a specific “tombstone” event in Kafka. A downstream Flink job detects this tombstone and issues an immediate hard delete command to the vector database.
This ensures sensitive data is removed from the AI’s memory instantly, maintaining regulatory compliance.
How to detect and measure context drift in RAG
You can’t fix what you don’t measure. Traditional accuracy metrics aren’t enough. You need to measure the timeliness of your context.
Measure freshness with mean time to index (MTTI)
Engineering teams should track Mean Time to Index (MTTI). This measures the elapsed time between a data change in the source system (e.g., COMMIT timestamp in PostgreSQL) and that change becoming searchable in the vector database.
Batch RAG MTTI: Hours to Days.
Streaming RAG MTTI: Seconds to Minutes.
Use RAG triad metrics: context precision, context recall, and faithfulness
Adopt the “RAG Triad” metrics to isolate retrieval failures:
Context Precision: Is the retrieved information actually relevant to the query?
Context Recall: Did you retrieve all the relevant information needed?
Faithfulness: Did the LLM answer strictly based on the retrieved context?
Test for drift with golden sets (freshness QA pairs)
Create a “Golden Set” of QA pairs specifically designed to test freshness. Include a question about a policy that changed yesterday. If the RAG system answers with the old policy, you’ve confirmed Stale-Context Drift.
Add RAG observability: trace answers to chunks and document versions
Implement tracing that connects the LLM’s response back to the specific retrieved chunks. You need to see exactly which document version and timestamp generated an answer.
If an answer is wrong, you should be able to click a trace and see, “This answer was generated using a chunk from Policy_v1.pdf indexed 3 days ago.”
Context drift checklist for drift-resistant RAG
Audit your architecture against this checklist:
Freshness (MTTI): Is your vector database updated via batch jobs or real-time streams? Target an MTTI of <1 minute for critical data.
Relevance: Are you enriching chunks with metadata (Time, Author, Version) using stream processing before indexing?
Governance: Do you use a Schema Registry to ensure data quality and compatibility across the pipeline?
Traceability: Can you trace a hallucinated answer back to the specific source record and its timestamp?
Deletions: Does your system handle hard deletes instantly via CDC tombstones for GDPR compliance?
Conclusion: build drift-resistant RAG with streaming data pipelines
Context drift is what happens when you try to serve dynamic AI needs with static data architectures. No amount of prompt engineering can fix a system that retrieves outdated or irrelevant facts.
The freshness and quality of the data streams feeding your RAG application ultimately define its quality.
For organizations struggling to keep context current, the path forward is clear: treat data as a continuous stream. Connect, process, and govern data in motion. That’s how you build a foundation for real-time AI that stays grounded in the present reality.
Frequently asked questions
What is context drift in RAG?
A: Context drift occurs when the content retrieved for the LLM is outdated or semantically off-target, so the model generates a confident answer grounded in the wrong context.
How is context drift different from an LLM hallucination?
A: A hallucination is the model inventing facts without support. Context drift is a grounded error where the model follows the retrieved sources, but those sources are stale or irrelevant.
What are the two types of context drift?
A: Stale-context drift (the index is behind the source of truth) and relevance drift (retrieved chunks are “similar” but not actually correct for the query).
What causes stale-context drift in production RAG systems?
A: Most commonly, batch ETL indexing that updates the vector database on a schedule, creating a time gap between operational changes and what the RAG system can retrieve.
What causes relevance drift in vector search?
A: Weak semantic signals from raw text embeddings, poor chunking, and missing metadata/governance. This makes “nearest neighbors” mathematically close but contextually wrong.
How do you measure freshness in a RAG pipeline?
A: Track Mean Time to Index (MTTI): the time from a source-system commit to the moment that change becomes searchable in the vector database.
How can I reduce context drift without changing the LLM?
A: Improve the retrieval layer: use CDC + streaming updates, enrich chunks with entities/version/time metadata, enforce schemas, and add traceability from answers back to indexed sources.
Why are deletes (GDPR/PII) hard in RAG, and how do you handle them?
A: Vector indexes often lag behind source deletions. Use CDC tombstone events to trigger immediate hard deletes in the vector database so removed data can’t be retrieved.
What metrics help isolate retrieval problems vs generation problems?
A: Use the RAG Triad: context precision, context recall, and faithfulness to determine whether failures come from retrieval quality or model behavior.
What’s the fastest architectural fix for context drift?
A: Replace “snapshot and sync” batch indexing with event-driven streaming (CDC → Kafka → stream processing → vector DB) to keep the index aligned with real-time operational data.